GPT-6.2 Astra scores 174 on the Epoch Capabilities Index (ECI), on par with Fable 5.2 and joining it above what the pre-Astra trend for reasoning models would have predicted.
This is based on testing we did prior to launch using only our own benchmarks. The ECI is continually updated as more benchmark results become available, and so these values may change in the future.

We ran GPT-6.2 Astra on an updated version of ‘Epoch Automation Reports’, our benchmark of realistic tasks drawn from Epoch AI’s own work. Here, GPT-6.2 Astra fell behind Fable 5.2, despite tying on ECI, and improved only slightly over GPT-6 Astra.
On relatively simple research projects, 6.2 Astra failed to target the core question and iterate effectively. On our AI data center research task, 6.2 Astra was overly cautious and omitted critical estimates, which would be unacceptable for a contractor.
Its writing was relatively strong compared to the other models we evaluated, but still below Epoch AI’s standards. We will release a full report on our updated version of Epoch Automation Reports in another post.

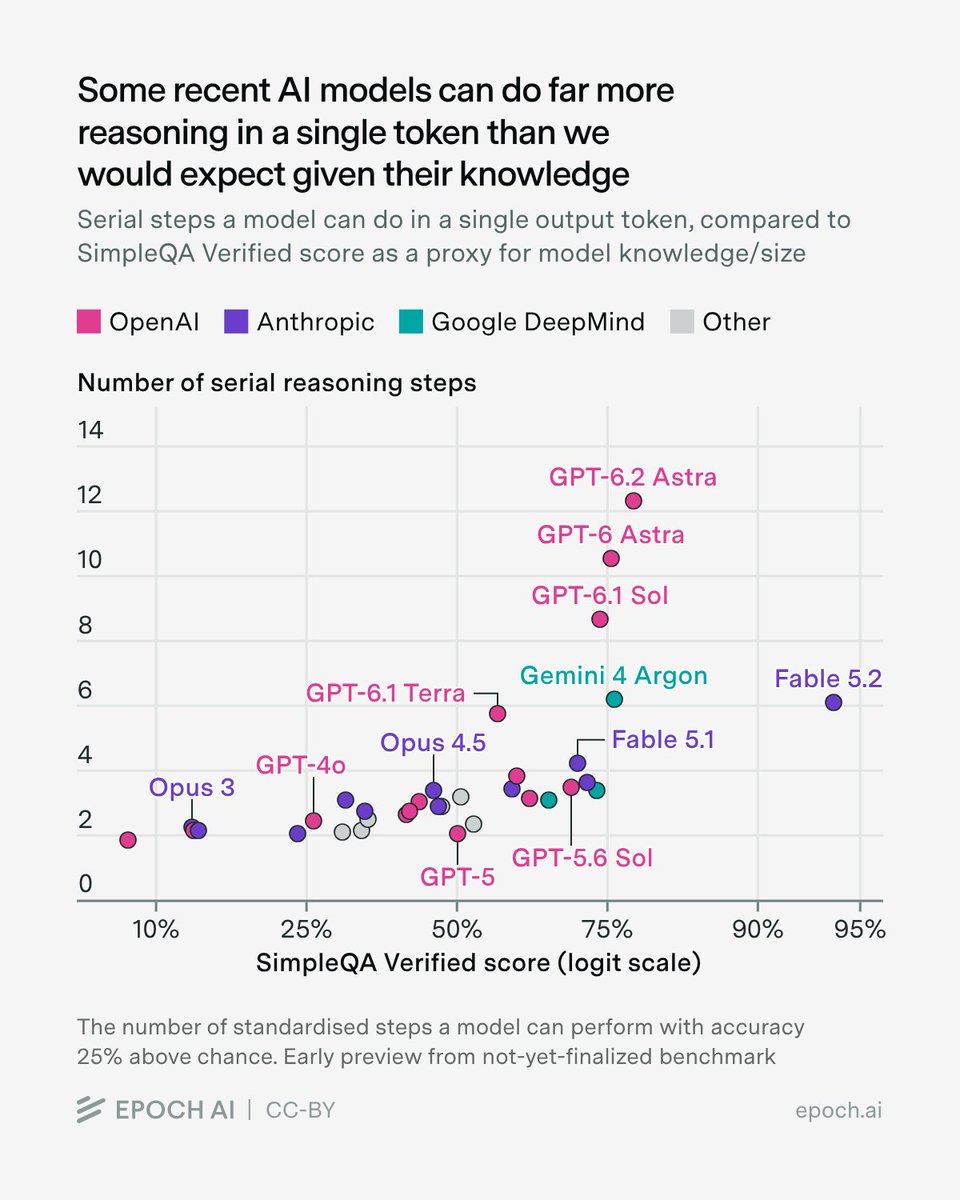
We also evaluated how many serial reasoning steps GPT-6.2 Astra can do in a single output token (without chain of thought). It can perform 12.3 steps, versus 10.5 for GPT-6 Astra and 8.6 for GPT-6.1 Sol, the previous highs. We measure the number of steps models can perform at an accuracy of 25% above chance, where each step is normalized for complexity.
Before GPT-6 Astra’s release, the most capable model was Claude Fable 5.1, which is able to perform only 4.2 serial steps. The oldest model we assessed is Claude Opus 3, which performed 2.3 steps.
This capability is notable because models that can do complex reasoning without any chain of thought may be harder to monitor.
We hope to finalize this and other measurements of more abstract model capabilities, and release them in the coming weeks.
GPT-6.2 Astra sets a new record on FrontierMath Erdős, our benchmark of handpicked math problems, unsolved as of August 2026. With a ~$240 budget per question, 6.2 Astra produced solutions to 7/68 of the problems, each formally verified in Lean, including one for which no prior solution was known. The previous record was 3/68, set by GPT-6.1 Sol.
See our full benchmark results for GPT-6.2 Astra here: epoch.ai/models/gpt-6-2


Missing some tweets in this thread? Or failed to load images or videos? You can try to .